
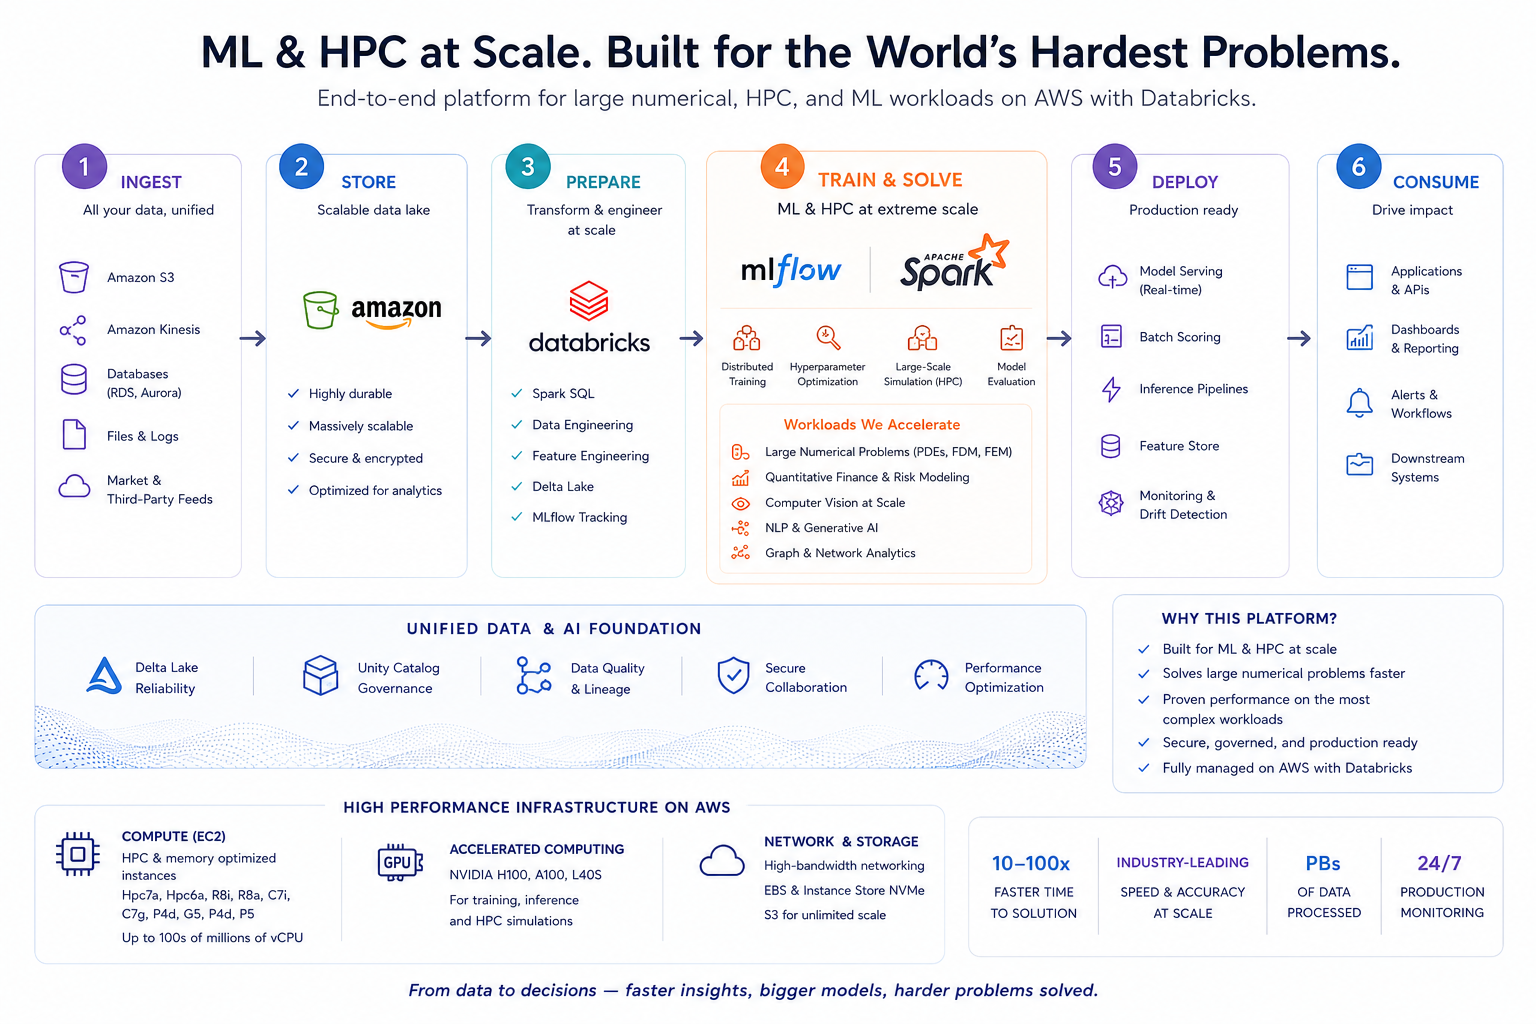
We are a machine learning research firm working at the intersection of high-performance computing and quantitative finance. We develop end-to-end models that ingest vast amounts of data each day, delivering robust, production-grade insights and truly accomplishing machine learning at scale. Our technology stack includes Spark clusters with thousands of cores and high-performance computing hardware that solve very large machine learning and nonlinear optimization problems in mere seconds.
About
Projects
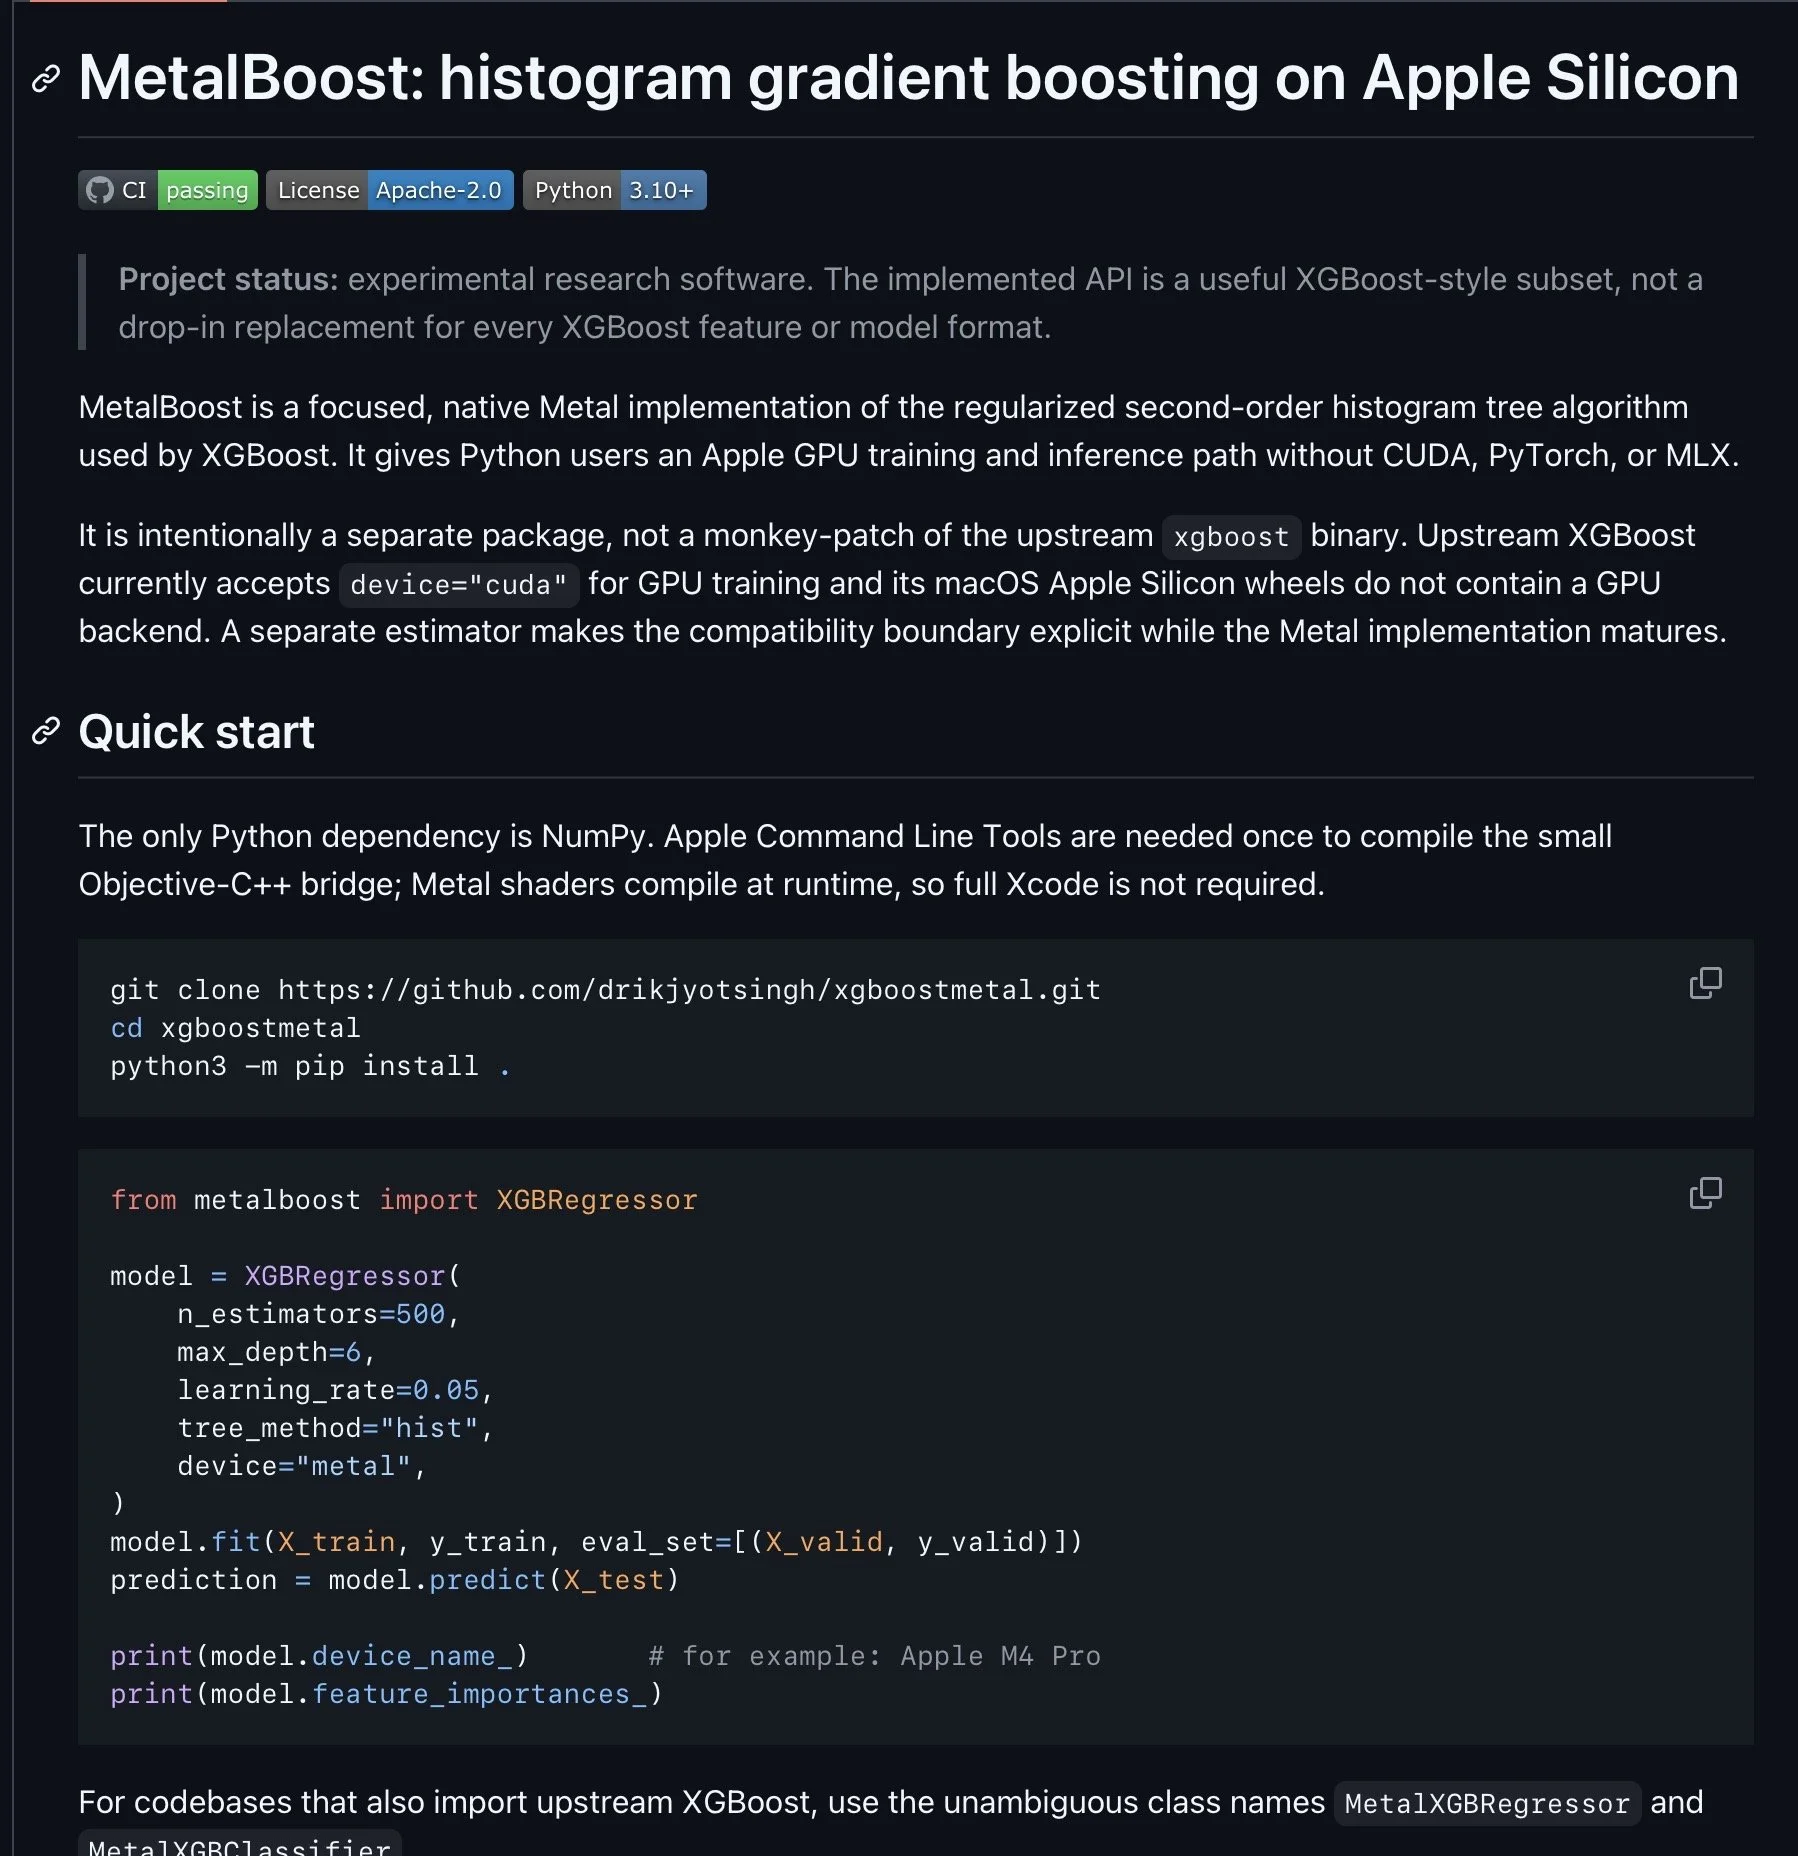
MetalBoost (Open Source)
An implementation of Gradient Boosted Trees specifically for Apple Silicon.
Machine Learning Based Stock Price Valuation and Prediction (Proprietary)
Using massive parallel computing to analyze petabytes of stock-related data to predict future stock prices with high accuracy.
Models run across custom built HPC clusters that constantly ingest new data and update predictions.
The screen capture below is a real live screen recording from our predicting the world state custom ML solution that ingests PBs of data from multiple markets across the world and simulates prices across these markets and sectors.
(Please note that IMRC does not currently accept funding from the public / outside investors.)
MetalBoost: A Custom Gradient Boosting Library specifically for Apple Silicon
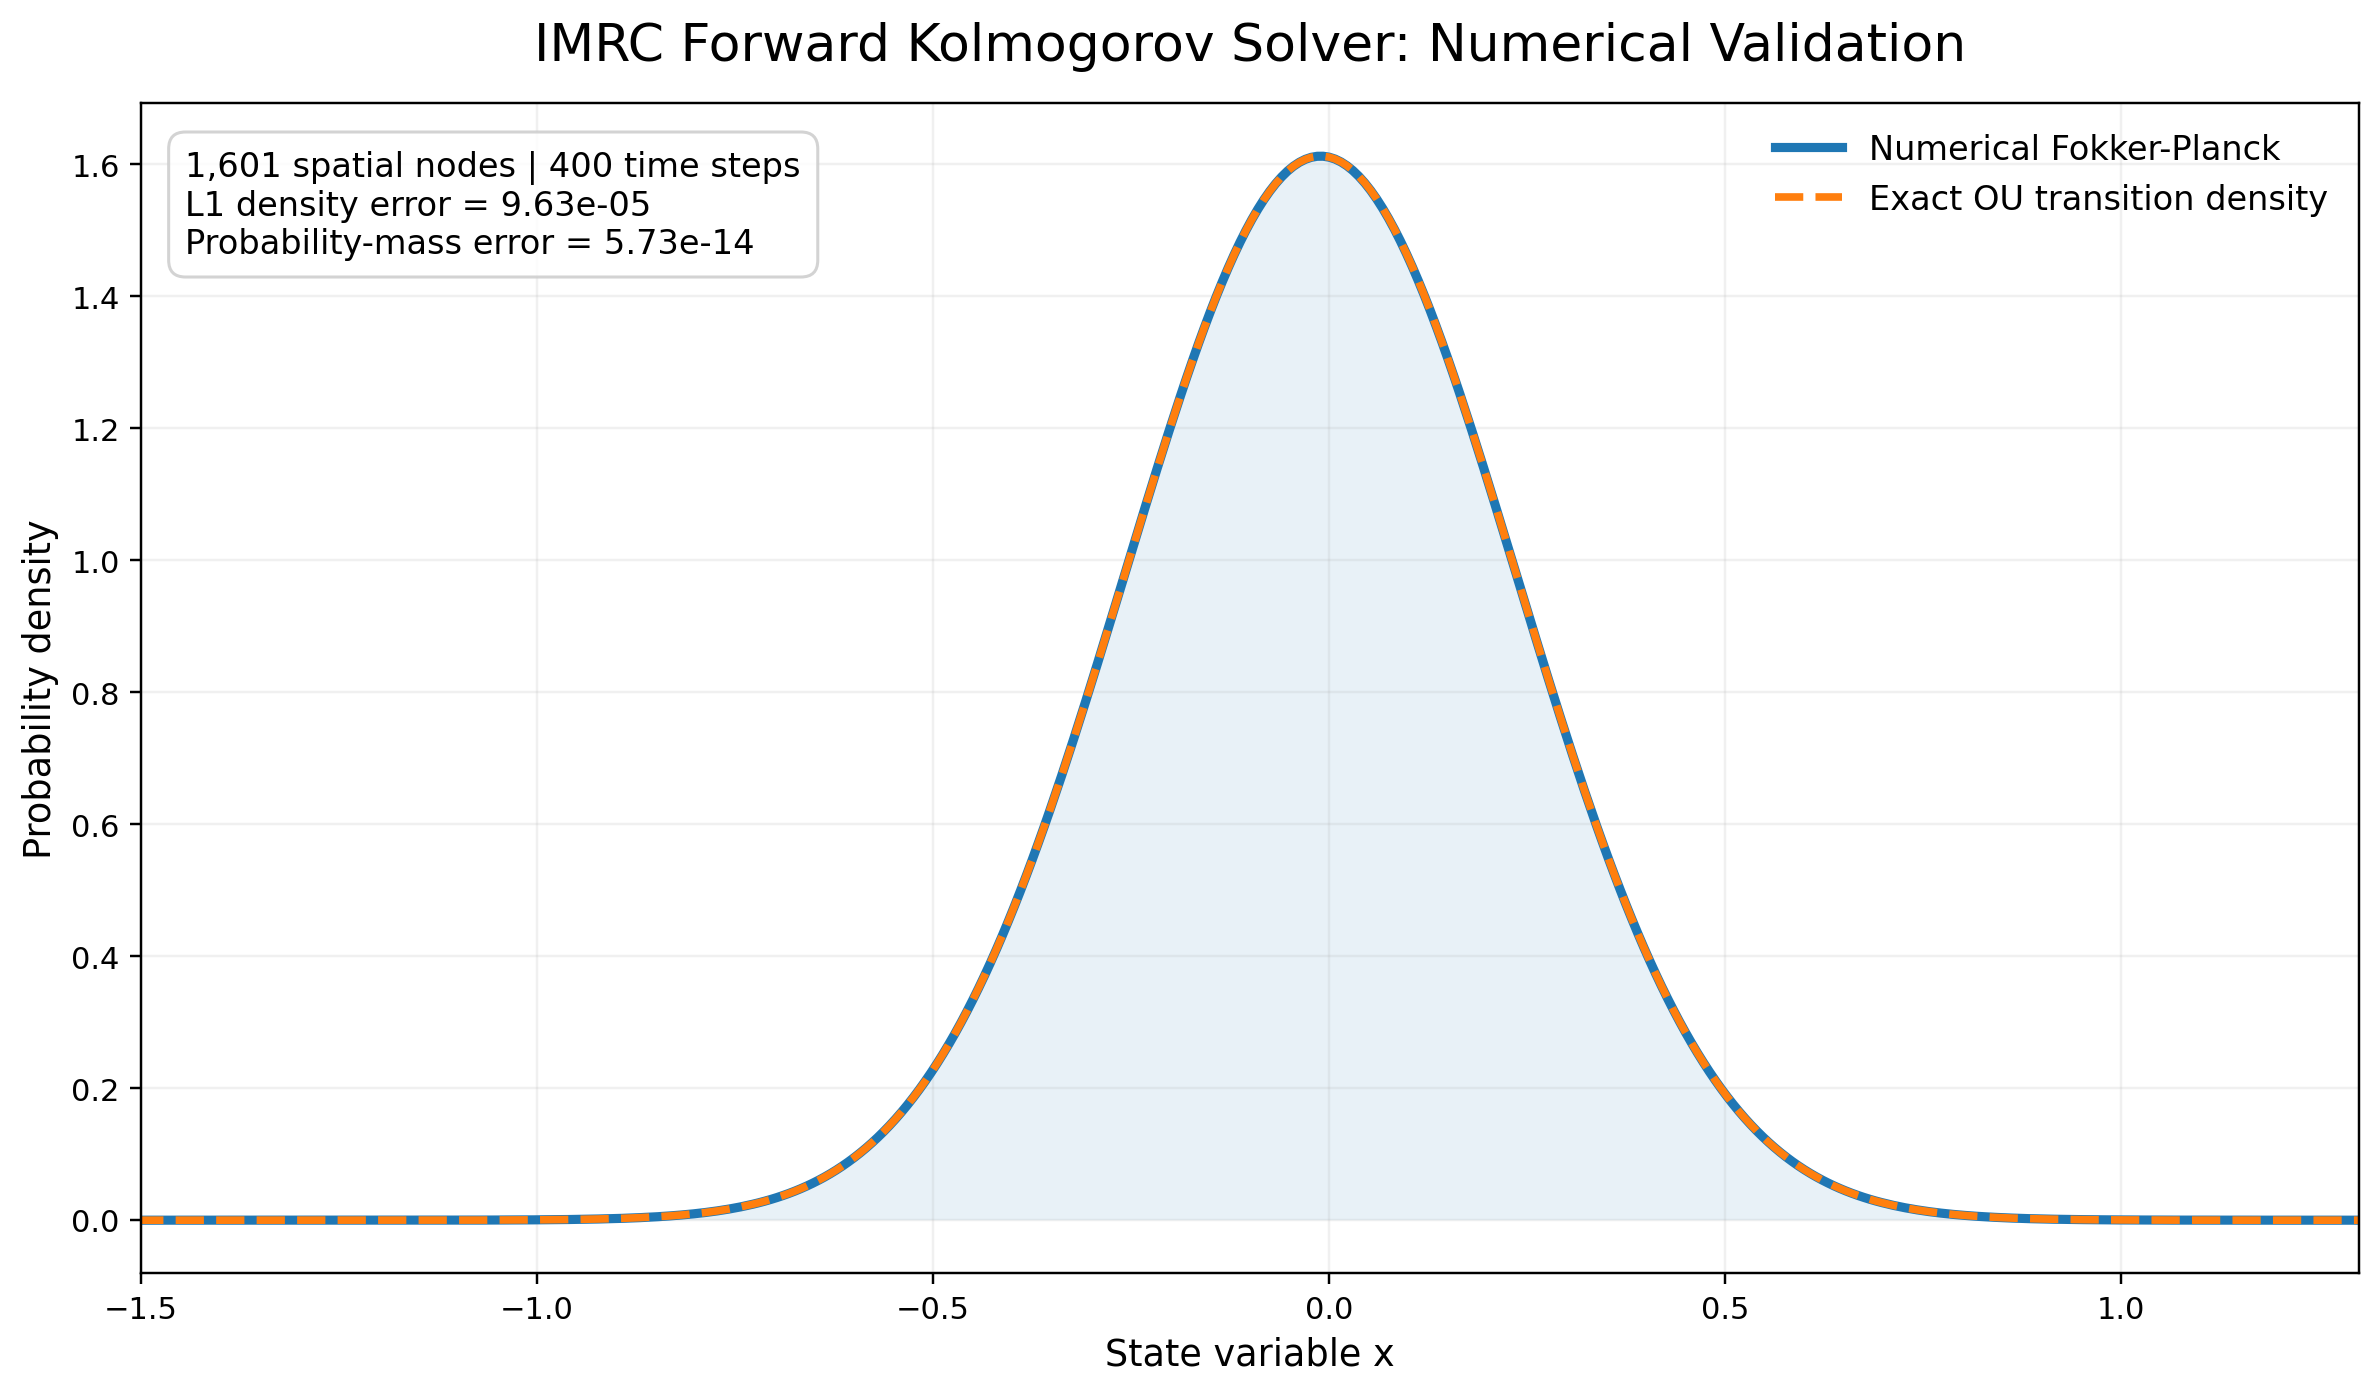
HPC Spark-based Kolmogorov/Fokker-Planck PDE Solvers (Proprietary)
We use Databricks and PySpark to distribute large-scale numerical PDE solving across parallel compute clusters.
In one benchmark, 10,000 forward Kolmogorov equations evolved 6.4 billion grid-time states in just 5.5 seconds.
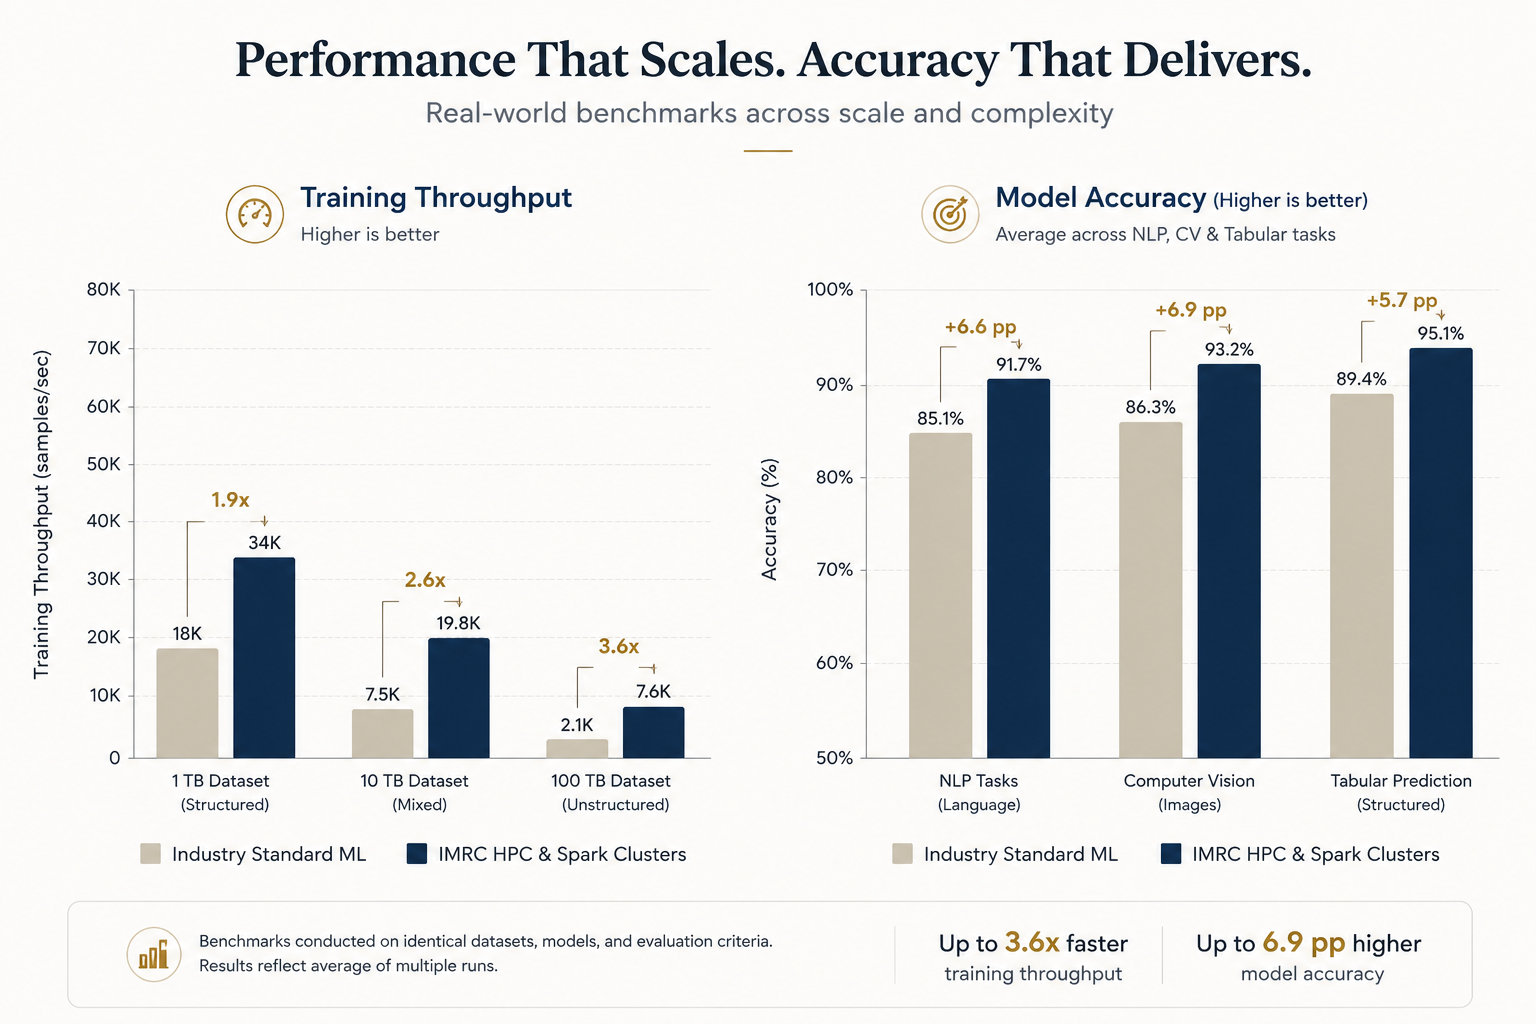
Machine Learning At Scale
Some of Our Current Infrastructure
| CPU Platform | Max Cores | Max Memory | Typical Role |
|---|---|---|---|
| AMD EPYC Zen 5 | 192 | 768 GB | Spark executors, ML training, HPC |
| AMD EPYC Zen 4 | 192 | 768 GB | Distributed compute |
| Intel Xeon 6 | 192 | 3 TB | SQL analytics, lakehouse, large JVM workloads |
| Intel Xeon Ice Lake | 64 | 1 TB | NVMe accelerated processing |
| AWS Graviton4 | 192 | 1.5 TB | ARM compute cluster |
| AWS Graviton3E | 64 | 128 GB | HPC simulation |
| Apple Mac Mini Pro M4 | 5 x 12 = 60 | 24 GB x 5 = 120 GB | ML Prototyping |
| GPU Platform | Memory | Architecture | Primary Workloads |
|---|---|---|---|
| NVIDIA H100 | 80 GB | Tensor Core | Foundation models |
| NVIDIA A100 | 40 / 80 GB | Tensor Core | Deep learning |
| NVIDIA L40S | 48 GB | RTX | Inference |
Where We Are Located
Toronto Office
100 University Avenue, 5th Floor
Toronto, Ontario, M5J 1V6
New York Office
135 Madison Ave, 5th Floor
New York, NY 10016